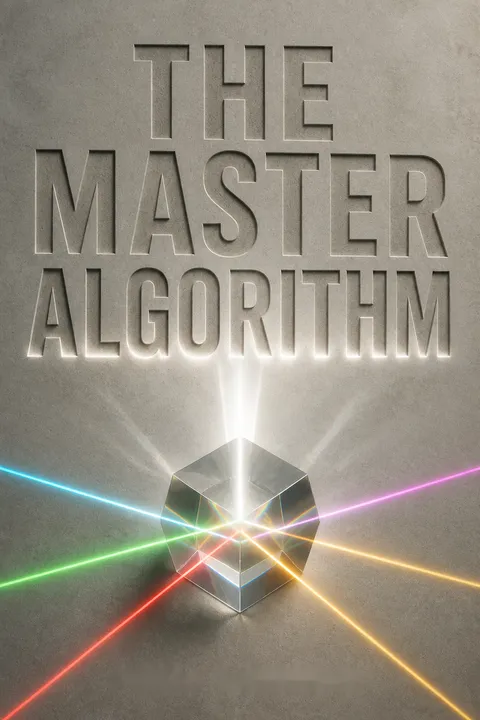


Key Takeaways
Let data teach computers the rules people cannot reliably write by hand.
Learning changes programming. A conventional program gives a computer explicit instructions. A learner instead uses examples, and sometimes desired outcomes, to construct a model that maps inputs to outputs. That distinction matters wherever rules are too numerous or difficult to spell out. People can drive or recognize handwriting, for example, without being able to describe every step; a learner can infer useful procedures from examples.
Examples are already everywhere. The book points to spam filters, search rankings, product recommendations, and cars learning to stay on the road. The same learning method can serve very different tasks when supplied with different data. That makes machine learning a way to automate not just work, but parts of the process of creating software.
The shift is from encoding a solution to defining a task and supplying evidence. That changes who can build useful systems: domain experts may contribute examples even when they cannot program the solution. It also changes where errors originate. A hand-coded rule can be inspected directly, while a learned model depends on its training examples, its design, and the objective used to judge success. The book’s striking claim that computers can learn skills people cannot explain is compelling, but learning from examples is not learning without human choices.
A Master Algorithm would unify learning, but finite data always needs assumptions.
The unifying ambition. Domingos proposes a hypothetical general-purpose learner, the Master Algorithm, that could derive knowledge across fields from data. It is a research goal, not a machine the book claims already exists. The ambition is illustrated by personalized cancer treatment: finding an effective drug could require combining tumor mutations, a patient’s history, drug effects, and biological knowledge that no single clinician can hold in full.
Universality has a catch. A learner may be able to approximate any function if supplied with enough data, but that amount may be infinite. With finite data, it must make assumptions about which patterns are plausible. A universal learner would therefore need a way to combine data with assumptions while remaining useful across many kinds of problems.
The Master Algorithm is valuable as a research compass even if no single method reaches the destination. It asks whether successful approaches share a learnable core, rather than treating every application as an isolated engineering project. The cancer example makes the aspiration concrete: integration matters as much as prediction. Yet “all knowledge” is a very strong claim. A learner can only infer what its representations and evidence make expressible, and some discoveries require experiments that have not yet been performed.
Choose assumptions openly, because data alone cannot tell past from future.
The induction problem. Hume’s problem of induction asks why observations already made justify predictions about cases not yet seen. The book illustrates it with someone trying to predict a friend’s answer to a date invitation. Several different rules can explain the few past yeses and nos, yet those rules predict different answers tonight. More data helps, but it cannot rule out an unobserved factor or a change in circumstances.
No free lunch. Wolpert’s theorem gives this difficulty a mathematical form: averaged over all possible worlds, no learner beats random guessing. A learner succeeds in the world we inhabit because it has assumptions that fit that world. Those assumptions may be prior knowledge, a model’s structure, or a preference for certain patterns. Learning is not data speaking by itself; it is evidence interpreted through a lens.
This is a useful antidote to the idea that large datasets automatically produce objective answers. Every model privileges some regularities over others, even when its designer tries to remain neutral. Making those commitments visible can improve both scientific scrutiny and public accountability. The limit is that explicit assumptions do not make them correct. They still need testing, revision, and comparison with alternatives, especially when the costs of a mistaken prediction fall unevenly on different people.
Test predictions on unseen cases before trusting a model's impressive fit.
Fit can mislead. Overfitting occurs when a learner finds patterns in its training examples that do not hold in the world. A model can match every example and still predict badly. The book recounts a tank detector that appeared perfect on training and test images, but had learned to distinguish lighter images from darker ones, not tanks from other vehicles. The images’ backgrounds had accidentally supplied the shortcut.
Reserve evidence. A practical check is to divide available data into a training set and a held-out test set. The learner sees the first, while the second provides a less biased estimate of its performance on new cases. Models can also fail through excessive rigidity, or bias, and excessive sensitivity to the training sample, or variance. More flexible models may reduce the first while worsening the second.
The tank example captures a general danger: a model may exploit a correlation that is predictive in a dataset but irrelevant to the question being asked. Held-out testing is essential, but it is not a guarantee. A test set can share the same hidden flaw as the training data, and real-world conditions can change after evaluation. Trust therefore depends not only on a score, but on checking how the data was collected, what errors matter, and whether performance persists in the settings where decisions will be made.
Borrow logic, brains, evolution, probability, and analogy; each sees a different pattern.
Five research traditions. Domingos organizes machine learning into five “tribes,” each focused on a different route to learning. Symbolists use logic and inverse deduction to build rules from facts. Connectionists adjust networks of artificial neurons through backpropagation. Evolutionaries search across candidate programs using mutation and genetic algorithms. Bayesians update probabilities as evidence arrives. Analogizers use similarity, as in nearest-neighbor methods and support vector machines.
Each solves part of the puzzle. Logic can combine prior knowledge, but struggles with ambiguity. Neural networks learn complex patterns, but their reasoning can be hard to interpret. Probability handles uncertainty, while analogy can transfer insight from similar cases. Evolution searches possible structures. The book’s point is not that one tribe wins, but that a broad learner may need strengths that these approaches developed separately.
The five-part map makes a fragmented field easier to understand and encourages researchers to borrow ideas across intellectual boundaries. It also discourages one-method thinking: a system that predicts images well need not reason well about relationships or uncertainty. Still, the traditions are not simply interchangeable ingredients. Their assumptions, computational demands, and definitions of success differ. Combining them requires deciding what representation can express, what evidence counts, and how to resolve conflicts, not merely placing algorithms side by side.
Unify learners by combining what they represent, reward, and search for.
Three design choices. Any learner needs a representation for possible models, an evaluation measure for judging them, and an optimizer for searching among them. A rule learner represents knowledge in logic; a neural network uses connected units; a support vector machine uses selected examples and their similarities. Their evaluation measures and search procedures differ, too. The book uses these common parts to show how the tribes might be compared and combined.
A proposed bridge. Markov logic networks, or MLNs, pair logical formulas with weights. Logic supplies expressive relationships, while weights allow a formula to be more or less likely rather than simply true or false. Domingos’s Alchemy system implements this approach as a candidate unifier. It is not presented as the completed Master Algorithm: scaling it and making it easier to use remain problems.
The representation, evaluation, and optimization lens is practical because it turns “Which algorithm should be used?” into a sharper set of questions. Can the model express the relevant relationships? Does its score reflect the real objective? Can the search find a useful solution within available resources? MLNs address a genuine divide between crisp rules and uncertain evidence. But greater expressiveness can increase computational cost and make systems harder to inspect. Unification is therefore a tradeoff, not a free upgrade.
Let machines discover structure and learn from the consequences of their actions.
Learning without labels. Much learning begins without anyone marking each example with the right answer. Clustering groups similar observations; dimensionality reduction compresses many measured features into a smaller set of informative dimensions. The expectation-maximization algorithm, or EM, alternates between estimating hidden group memberships and improving the model of each group. This is useful when the data contains structure but no explicit labels.
Learning through action. Reinforcement learning improves behavior from rewards and penalties, including rewards that arrive much later than the action. Arthur Samuel’s checkers program learned to evaluate board positions, then used those estimates to choose moves, improving through play. Unlike a supervised learner given the right answer at each step, a reinforcement learner must explore, discover consequences, and balance trying new actions against repeating promising ones.
These methods widen the picture of learning beyond memorizing labeled examples. Clustering finds organization in observations, while reinforcement learning connects behavior with delayed outcomes. Together, they suggest why interaction can teach what passive observation cannot: actions reveal how the environment responds. But exploration has costs. A checkers program can afford to make mistakes; a medical system or robot operating near people cannot explore recklessly. The consequences of experimentation must shape how much autonomy a learner is given.
Model relationships, because influence and biological function rarely live in isolated records.
From rows to networks. Many prediction methods treat examples as separate records. Relational learning instead represents entities and their connections, then uses repeated relationship patterns to make predictions. If flu spreads through friendships, knowing that a patient’s contacts are ill provides evidence about the patient. A template such as “friends of infected people may also be infected” can apply across many pairs without learning a separate rule for each pair.
Why it matters. The same approach can model links between people, web pages, genes, proteins, and chemical processes. The book describes using network data to identify influential members of a product-review community. It also argues that understanding a living cell requires modeling interactions among genes and molecules, not just measuring isolated correlations. Relationships can carry predictive information that individual attributes miss.
Relational models recognize that social and biological systems are not collections of independent cases. Their structure can explain why a pattern spreads, repeats, or changes when one part of the network changes. This perspective is especially useful when labels are sparse, since connected observations can provide indirect evidence about one another. A key caution is that association in a network does not by itself prove influence or cause. The model’s relationships need careful interpretation, and causal claims may require evidence beyond observed links.
Control your data trail before algorithms turn it into someone else's leverage.
Data teaches the system. Every interaction can both serve an immediate purpose and provide information about the person using the system. The book describes the 2012 Obama campaign consolidating voter data and running 66,000 election simulations nightly to guide calls, visits, and messages. In commerce, recommendation systems use accumulated behavior to shape what customers see, and the resulting choices generate more data for future predictions.
Access is power. Domingos argues that people should be able to understand, control, and benefit from the models built from their data. He imagines personal data services or data unions that pool experiences while protecting individuals’ interests. He also makes the case for sharing data when it can help others, such as cancer patients contributing treatment histories. The challenge is to share for collective benefit without surrendering control to organizations with different incentives.
The political campaign example shows that prediction is not merely descriptive: it can help decide whom to contact, what to say, and where to spend effort. Data access therefore shapes influence as well as convenience. The proposed data banks and unions offer an institutional response, not just advice to individual users. Their promise depends on credible governance: an organization entrusted with intimate records could itself become a powerful intermediary. Control must include meaningful limits on use, not simply a promise of benevolent handling.
Pair human expertise with algorithms, then audit the goals they optimize.
Work changes unevenly. The book argues that narrow tasks can be easier to automate than jobs that demand broad context. Algorithms may assess credit applications or recommend products, while physical navigation and judgment in unfamiliar settings remain difficult. Rather than treating automation only as a contest, Domingos recommends combining human expertise with machine capability, as in the “centaur” chess players who use both person and program.
Objectives matter. A learner optimizes the evaluation it is given, not necessarily the outcome people actually want. A recommendation system can keep proposing items that resemble a recent purchase even when the customer has no need for more of them. The author sees this mismatch, rather than machine ambition, as a central risk. People must specify goals carefully and check whether systems serve them in practice.
The “human with machine” framing is more useful than a simple replacement narrative because it directs attention to task design: which parts are repeatable, and which require judgment, context, or accountability? The warning about objectives reaches beyond technical design. An apparently successful model can still produce harmful outcomes if its score rewards the wrong proxy. Human oversight helps only when people can understand the decision, challenge it, and change the incentives that generated it.
Analysis
The book’s central achievement is conceptual: it makes machine learning legible as a family of methods that infer models from data, then asks whether their shared structure can support a general theory of learning. Its narrative moves from everyday applications, through Hume’s challenge to induction, into five research traditions, and finally toward Markov logic networks as a possible synthesis. The throughline is that data never works alone. Representation, prior assumptions, evaluation, and search shape what a learner can discover.
That argument remains more durable than the literal promise of one algorithm capable of deriving all knowledge. The five traditions do not simply offer interchangeable tricks. They encode different ways to define a problem, and their combination can make a system more expressive while increasing computational and interpretive burdens. The book recognizes some of this in its description of Alchemy as incomplete, but its grand ambition sometimes outruns the evidence supplied for universality. A unifying framework can guide research without proving that every kind of knowledge is reducible to one practical procedure.
The strongest practical lesson is therefore not to wait for a universal machine. It is to ask which assumptions a deployed learner makes, whether its evaluation reflects the real goal, and whether its performance survives unfamiliar cases. These questions connect technical quality to institutional responsibility. Search engines, campaign tools, medical models, and recommendation systems do not merely predict; they shape which options become visible and which actions receive attention. Understanding machine learning is consequently a form of civic literacy as well as technical literacy. The book’s futurism is most persuasive when it directs attention back to choices people can make now: what data to collect, what to optimize, and who gets to inspect the result.
Review Summary
The Master Algorithm receives mixed reviews, with praise for its comprehensive overview of machine learning approaches and accessible explanations for non-experts. Many readers found it informative and thought-provoking, particularly in its discussions of AI's potential impact on society. However, some criticized the book for being overly technical in parts, repetitive, or lacking depth in certain areas. The author's optimistic view of AI's future and his proposal for a unified learning algorithm sparked both interest and skepticism among readers.
People Also Read



Glossary
Master Algorithm
hypothetical universal learnerDomingos’s name for a hypothetical general-purpose learning algorithm that could derive many kinds of knowledge from data, guided by assumptions and prior knowledge. The book presents it as a research ambition, not a finished technology. Its proposed value is unification: one learning framework could help explain and solve problems now approached with separate methods.
No free lunch theorem
no universally best learnerA result showing that, averaged across all possible data-generating worlds, no learning algorithm performs better than random guessing. A learner succeeds in a particular world because its assumptions suit that world. In practical terms, data alone cannot determine how to generalize; the model’s built-in preferences and prior knowledge matter.
Overfitting
mistaking sample quirks for patternsThe error of learning patterns that match the training data but do not generalize to new cases. A model may memorize unusual details, noise, or accidental correlations and appear highly accurate on examples it has seen. Testing on held-out data helps detect this, though flaws in data collection or changes in conditions can still mislead.
Inverse deduction
infer rules from conclusionsA symbolist learning method that works backward from facts and conclusions to propose rules that would allow the conclusions to be deduced. Rather than learning only from isolated examples, it can use existing rules and knowledge to fill gaps in reasoning. Its expressive power is useful, but searching among possible rules can be computationally difficult and vulnerable to noise.
Backpropagation
adjust network weights from errorA method for training a multilayer neural network. It compares the network’s output with the desired output, sends an error signal backward through the network, and adjusts connection weights to reduce future error. This lets networks learn complex patterns that a single perceptron cannot represent, though optimization can be difficult and learned models may be hard to interpret.
Markov logic network
weighted logical rulesA model that combines logical formulas with weights indicating how strongly each formula tends to hold. Applied to a set of entities, its formulas generate features for possible states, and the weights define their relative probabilities. It can represent uncertain relationships while retaining logic’s ability to describe general rules among multiple entities.
Expectation-maximization algorithm
learn with hidden informationAn iterative method for estimating a statistical model when some information is missing, such as the group membership of observations. It alternates between estimating the likely hidden assignments and updating the model parameters using those estimates. Each round improves the model’s likelihood until the procedure reaches a local maximum.
Reinforcement learning
learn from action and rewardA learning approach in which an agent interacts with an environment, observes the consequences of actions, and seeks to increase future rewards. Feedback may arrive long after an action, so the learner estimates the value of states and actions, not just immediate outcomes. It must balance exploring unfamiliar choices with using actions that already appear promising.
Relational learning
learn patterns among connected entitiesA family of methods that learns from data represented as networks of entities and relationships rather than independent records. Reusable relationship patterns can support predictions across many people, objects, or biological components. Because connected entities provide indirect evidence about one another, relational learning can make use of sparse labels and model interaction patterns.
Support vector machine
maximum-margin classifierA similarity-based learning method that classifies examples by finding a decision boundary with the widest possible margin between classes. The boundary is determined by a subset of training examples called support vectors. With an appropriate kernel, the method can represent curved boundaries by treating the data as if it were mapped into a higher-dimensional space.
Curse of dimensionality
learning difficulty from many featuresThe rapid increase in data and computational demands as the number of measured attributes grows. In high-dimensional spaces, examples become sparse and ordinary intuitions about distance and similarity can fail. Irrelevant features can obscure useful similarities, while even relevant features may require far more training examples to learn reliable patterns.
FAQ
What's The Master Algorithm about?
- Exploration of Machine Learning: The Master Algorithm by Pedro Domingos explores the concept of a universal learning algorithm that can derive knowledge from any data set.
- Five Tribes of Learning: It categorizes machine learning into five main schools: Symbolists, Connectionists, Evolutionaries, Bayesians, and Analogizers, each with its own approach.
- Real-World Applications: The book illustrates how machine learning impacts various aspects of life, from online recommendations to medical diagnoses.
Why should I read The Master Algorithm?
- Understanding Machine Learning: The book provides a clear introduction to machine learning concepts, suitable for both technical and non-technical readers.
- Future Implications: It discusses the potential future of machine learning and its societal implications, helping readers navigate the digital landscape.
- Inspiration for Innovators: Domingos encourages readers to think critically about algorithms and consider contributing to the field of machine learning.
What are the key takeaways of The Master Algorithm?
- Quest for a Universal Algorithm: The central theme is the search for a "Master Algorithm" that can learn from any data and solve any problem.
- Integration of Learning Approaches: Emphasizes the importance of integrating the strengths of the five tribes to create a more powerful algorithm.
- Real-World Impact: Highlights how machine learning is transforming industries and everyday life, emphasizing the need to understand these changes.
What are the best quotes from The Master Algorithm and what do they mean?
- “You can’t control what you don’t understand.”: Emphasizes the need for understanding machine learning algorithms as they influence decision-making.
- “Machine learning is something new under the sun: a technology that builds itself.”: Highlights the transformative potential of machine learning, where algorithms can create new algorithms.
- “All knowledge—past, present, and future—can be derived from data by a single, universal learning algorithm.”: Suggests that a Master Algorithm could unlock vast amounts of knowledge.
What are the five tribes of machine learning discussed in The Master Algorithm?
- Symbolists: Focus on manipulating symbols and logical reasoning, using inverse deduction as their master algorithm.
- Connectionists: Use neural networks inspired by the brain's structure, with backpropagation as their master algorithm.
- Evolutionaries: Apply natural selection principles, using genetic programming to evolve solutions over time.
- Bayesians: Emphasize probabilistic reasoning, using Bayesian networks to model relationships and update beliefs.
- Analogizers: Learn by finding similarities between instances, often using nearest-neighbor algorithms.
How does The Master Algorithm define the concept of a Master Algorithm?
- Universal Learner: Envisioned as a single algorithm that can learn from any type of data and solve any learning problem.
- Combining Methods: Utilizes various learning techniques, such as genetic algorithms and gradient descent, to adapt to different contexts.
- Real-World Applications: Would have profound implications for fields like healthcare, finance, and education, leading to better decision-making.
How does The Master Algorithm relate to real-world applications?
- Healthcare Innovations: Machine learning can improve medical diagnoses and treatment plans by analyzing patient data.
- Business Efficiency: Companies use machine learning to optimize operations, predict customer preferences, and improve supply chain management.
- Personalization in Technology: Algorithms power personalized recommendations on platforms like Netflix and Amazon, tailoring content to individual preferences.
What is Hume’s problem of induction as described in The Master Algorithm?
- Challenge of Generalization: Questions how we can justify generalizing from observed instances to unobserved ones.
- Implications for Learning: Central to machine learning, as algorithms must generalize from training data to make predictions about new data.
- Need for Knowledge: Effective learning requires prior knowledge to guide the induction process, avoiding incorrect generalizations.
What is the significance of Bayes’ theorem in The Master Algorithm?
- Foundation of Bayesian Learning: Provides a framework for updating beliefs based on new evidence, central to Bayesian machine learning.
- Practical Applications: Used in medical diagnosis and spam filtering, combining evidence to make informed predictions.
- Connection to the Master Algorithm: Domingos argues that the Master Algorithm must incorporate Bayesian principles for effective learning.
How does The Master Algorithm address the exploration-exploitation dilemma?
- Balancing Strategies: Involves deciding whether to explore new options or exploit known ones for optimal learning outcomes.
- Genetic Algorithms as a Solution: Explore multiple hypotheses simultaneously, allowing for efficient search for optimal solutions.
- Real-World Implications: Crucial for developing algorithms that adapt to changing environments and make the best decisions.
What role does dimensionality reduction play in machine learning as discussed in The Master Algorithm?
- Simplifying Data: Techniques like principal component analysis (PCA) reduce variables while retaining essential information.
- Improving Performance: Focuses on important dimensions, helping algorithms perform better and faster, mitigating overfitting.
- Applications Across Fields: Used in image processing, natural language processing, and bioinformatics for efficient data analysis.
What are the limitations of the Master Algorithm?
- Dependence on Data Quality: Effectiveness is contingent on the quality and quantity of data available, risking inaccurate predictions.
- Complexity of Real-World Problems: May struggle with tasks requiring deep contextual understanding or nuanced reasoning.
- Ethical Considerations: Raises concerns about biases and responsible development as machine learning algorithms become more powerful.
Download PDF
Download EPUB
.epub digital book format is ideal for reading ebooks on phones, tablets, and e-readers.








