

Key Takeaways
Measure disagreement before searching for a culprit in bad decisions
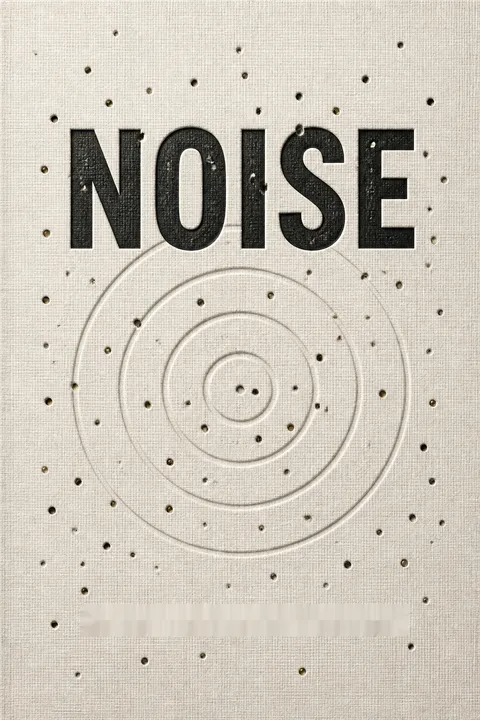
Two errors differ. Bias is a consistent drift away from the right answer. Noise is the scatter among judgments that should be similar. Imagine several teams aiming at the same target: one group can cluster together but miss the center, while another can be centered overall yet scatter widely. The first pattern is bias; the second is noise. Together, they make up judgment error. Scatter needs no answer key. A noise audit asks several qualified people to judge the same cases independently, then measures how far their answers vary. Doctors can disagree about a diagnosis even when nobody knows the true condition; the disagreement itself is observable. In asylum decisions, one judge admitted 5% of applicants while another admitted 88%, despite considering comparable cases.
The distinction matters because organizations often look for a culprit when a decision goes wrong: a careless employee, a bad incentive, or a distorted belief. Scatter can persist even when every participant is conscientious and trained. In measurement science, repeatability is a basic property of an instrument; human judgment deserves the same scrutiny. Still, agreement alone cannot certify correctness. A team can converge on the same mistaken answer, so measuring noise should complement, not replace, checks for bias and accuracy.
A random assignment can turn expert discretion into an expensive lottery
The case follows the person. Judge Marvin Frankel drew attention to defendants with similar crimes receiving radically different sentences. In one example, two men convicted of cashing counterfeit checks received fifteen years and thirty days. Studies asking judges to sentence identical case descriptions confirmed that large disparities were routine. Sentencing guidelines later narrowed those differences, and disparities rose again when the guidelines became advisory. Business has its own lottery. In an insurance company audit, executives expected underwriters' prices to differ by about 10%. The median difference was 55%; claims estimates differed by 43%. The right premium was uncertain, but assigning a case to one available employee rather than another clearly changed the result. Such inconsistency can cost money and undermine confidence in the institution.
The lottery metaphor exposes a quiet fairness problem: people often experience a decision as a verdict on their case, while the outcome may partly reflect who happened to be assigned. This resembles unequal treatment in public services, where access to a capable professional can matter as much as the formal policy. The strongest response is not automatically rigid control. It is first to learn whether the variation is consequential, then to choose a remedy suited to the task and its human stakes.
For prediction, cut scatter as seriously as systematic error
Error has two sources. For predictive judgments scored by mean squared error, overall error can be decomposed as bias squared plus noise squared. Bias is the average directional miss; noise is the standard deviation of individual misses. Reducing either by the same amount improves this error measure equally. In a sales forecast example, predictions averaged 44% when the eventual market share was 34%. The forecasts were both optimistic on average and spread out. Making them more consistent did not cure the optimism, but it still reduced total error. Use the equation carefully. It applies to predictions aiming at a true value, not automatically to choices where values and trade-offs define what counts as good.
The equation gives organizations a reason to measure scatter even before outcomes are known. It also clarifies why average performance can conceal costly mistakes: one overestimate does not compensate for another case being underestimated. Yet mean squared error assigns especially high penalties to large misses, a sensible choice in many forecasting tasks but not a universal account of harm. A missed diagnosis, an unnecessary test, and an unfair sentence do not have symmetric costs. Measurement should follow the consequences the institution actually cares about.
Your judgment changes with the judge, the moment, and the room
The same mind varies. Occasion noise is variation in one person's judgment of the same case across different moments. Doctors have changed diagnoses on a second review; wine judges gave identical scores to only 18% of wines tasted twice. Mood, fatigue, recent cases, and even weather can shift decisions. Asylum judges were 19% less likely to grant an application after approving the previous two. Groups add another layer. In experiments, a single early positive vote made later viewers more likely to approve a comment, and similar groups sometimes produced sharply different rankings of the same songs. Discussion can spread useful information, but it can also amplify the first confident opinion or push a group toward a more extreme version of its initial leaning.
These effects complicate the flattering idea that a considered opinion is a stable expression of expertise. The meeting room is part of the measurement instrument: who speaks first, what was just discussed, and how tired people are can shape the result. A practical implication is to record independent views before group discussion, then compare them openly. That is not an argument against deliberation. Discussion can surface missing evidence, but it works best when it does not erase the information people brought in separately.
A simple rule often beats an expert's shifting private formula
Consistency is a form of skill. In research comparing professional predictions with formulas using the same information, mechanical methods usually performed better. A review of 136 studies found formulas more accurate in 63, tied with people in 65, and less accurate in only eight. Even a simple equal-weight score can rival a carefully fitted model when the data set is small. The model's advantage is not always deeper insight; it applies the same rule to every case and avoids the judge's fluctuating attention and case-specific reactions. Rules have limits. A model can preserve biased historical data, ignore a decisive fact it was not given, or create harm through a poor threshold. It should support accountable judgment, not escape it.
The finding challenges a common intuition: a detailed human story feels richer than a formula, so it seems more accurate. But richness can be a source of inconsistency when the evaluator changes the weight of cues from case to case. This resembles reproducibility in science: a method that another person can apply is easier to test and improve. The important distinction is between prediction and the final choice. A model can estimate risk; society still has to decide what level of risk is acceptable.
Begin forecasts with the base rate, then adjust modestly
Start outside the story. The outside view treats a case as one member of a relevant class, rather than as a uniquely compelling narrative. Before predicting whether a particular executive will succeed, ask how often new executives generally remain in their roles. Then adjust that starting estimate using how diagnostic the individual evidence really is. This guards against matching a vivid profile directly to an extreme prediction. The future is partly unknowable. A competition using extensive family data still predicted individual events such as eviction poorly; the strongest model's correlation was .22. Predictions for broader measures, such as GPA, were better but limited. When evidence is weak, a forecast should stay closer to the class average. Extreme performance tends to move toward the average when its predictors are imperfect.
Narratives make outcomes feel inevitable after they happen. A base rate interrupts that hindsight effect by asking what tends to occur across comparable cases before this particular story is known. The approach is useful in hiring, planning, and medicine, where vivid details invite confident forecasts. Its weakness is the choice of reference class: an overly broad class washes out relevant differences, while a narrowly tailored class may simply disguise the original anecdote. The comparison group must be chosen and defended, not treated as self-evident.
Delay the verdict until evidence has been assessed independently
Keep the first impression out. Fingerprint examiners once identified Brandon Mayfield's print as a match to evidence from the Madrid train bombings; Spanish investigators later linked the print to someone else. Research found that contextual details about a suspect could change examiners' conclusions and even affect which print features they noticed. Linear sequential unmasking limits this risk by giving experts only the information needed for each step, recording early judgments, and keeping verification independent. Structure complex choices, too. The mediating assessments protocol breaks a strategic option into separate questions, such as financial prospects and management quality. Analysts assess these strands independently; decision makers review them before forming a final overall view.
The method protects against premature coherence, the mind's tendency to build a complete story from early scraps and then interpret new evidence in its favor. Information order is therefore a substantive design choice, not clerical housekeeping. Separating assessments also makes disagreement more informative: the board can see which issue divides members instead of arguing over a single blended impression. The safeguard requires care, however. Withholding irrelevant context is valuable; withholding information essential to a sound judgment would merely replace one distortion with another.
Average independent opinions, not opinions reshaped by the meeting
Separate, then combine. Averaging independent estimates reduces random variation: the more independent judgments included, the smaller the noise in their average. In a famous country-fair example, the average of 787 villagers' estimates of an ox's weight came within two pounds of its actual weight, even though no individual guessed exactly. A person can also make an independent second estimate after a pause or by deliberately considering a different explanation. Independence is essential. When people see others' answers first, they may herd toward an early opinion. A useful meeting sequence is estimate, discuss, estimate again. It lets participants learn from one another without allowing the first speaker to define the group's starting point.
Aggregation works like repeated measurement: independent errors tend to offset in the average, while correlated errors do not. That qualification is central. A room full of people who share the same assumptions can be confidently wrong, and open discussion before an initial vote can make their errors more alike. Conversely, diversity helps when it brings genuinely different information or expertise. The aim is not to suppress conversation, but to preserve independent signals long enough to combine them and then use debate to improve the evidence.
Give judgment a shared scale, anchored in concrete comparisons
Numbers need meaning. In a study of punitive damages, judgments expressed in dollars were extraordinarily noisy: 94% of their variation was attributed to noise. Converting each participant's awards into a ranking of the cases cut that share to 49%. People could compare which case deserved more punishment more reliably than they could invent an absolute dollar amount without an anchor. Guidelines clarify scales. The Apgar score assesses five aspects of a newborn's condition using simple, defined categories, reducing the room for divergent interpretations. Performance reviews have a similar problem: vague labels such as “excellent” invite different standards. Concrete examples, comparison cases, and behavior-specific descriptions help raters use a common frame.
A scale is not a neutral container. It can create disagreement even when people share a rough underlying impression, because words and numbers mean different things to different raters. Comparisons often work better because people can distinguish two cases more finely than they can assign each one an isolated score. But rankings answer relative questions, not absolute ones. If every employee meets a genuine standard, forcing a fixed percentage into a low category manufactures differences instead of measuring them.
Reduce avoidable noise, but price the human and institutional costs
Zero is not always best. Rules can shrink discretion and make repeated decisions more consistent; standards leave room for judgment but can produce wider variation. The right balance depends on the cost of errors, the burden of applying a rule, and whether the rule overlooks important circumstances. A rigid sentencing policy may reduce disparities yet treat unlike cases alike. A vague standard may preserve flexibility but make similar people face different outcomes. Choose the remedy deliberately. Noise reduction can also use guidelines, independent review, better scales, or aggregation, without replacing every human judgment with a formula. The authors' central proposal is decision hygiene: preventive procedures that reduce a broad range of errors even when the source of each error is unknown.
This is a stronger argument than simply declaring discretion bad. Procedural consistency protects people from arbitrary treatment, while the ability to explain a decision and be heard can itself matter. The design question is which safeguards reduce inconsistency without making the process cruel, opaque, or easy to game. A useful institution should make both error and exception reviewable: rules need revision when they fail, and discretion needs monitoring when it quietly becomes a lottery.
Analysis
The book's most important move is to make disagreement measurable without first settling who is right. That shifts attention from dramatic, explainable mistakes to the quieter variation produced by otherwise competent decision makers. The distinction is especially valuable in institutions that assign cases quasi-randomly, because inconsistency becomes both an accuracy problem and a fairness problem. Its examples also show why the phenomenon evades notice: each decision is encountered alone, then explained through a plausible story. Noise appears only when similar judgments are compared as a set.
The argument is strongest when it concerns prediction. If two forecasts target the same quantity, variation is evidence that at least some are wrong, and a stable model can remove arbitrary fluctuation. The case is more complicated for evaluative judgments, where there may be no single true answer. Treating the average judgment as a proxy for justice is analytically convenient, but consensus can encode shared prejudice, and principled disagreement can represent genuine moral conflict rather than a defect. Noise audits identify variation; they do not by themselves establish the right level of uniformity.
That distinction has practical consequences. A medical guideline can improve reliability when its criteria track meaningful evidence, while a rigid rule can produce a consistent mistake when its categories miss relevant context. Likewise, an algorithm may be more reproducible than a person without being more legitimate. The most defensible program is therefore not uniformity at any cost, but explicit measurement, a stated objective, and scrutiny of who benefits from remaining discretion. The book's emphasis on process is persuasive because it offers remedies between unaided intuition and total automation: independent assessments, shared scales, structured deliberation, and calibrated use of models. Its deeper lesson is institutional humility. Expertise may improve judgment, but confidence and fluency cannot demonstrate that comparable cases are being treated comparably.
Review Summary
Noise receives mixed reviews, with some praising its insights on decision-making variability and others criticizing its length and repetitiveness. Many find the concept of noise in judgments valuable, but some argue the book lacks novelty compared to Kahneman's previous work. Readers appreciate the practical applications in fields like medicine and law, but some find the writing style dry and overly academic. The book's emphasis on statistical thinking and decision hygiene is noted, though opinions vary on its overall impact and readability.
People Also Read








Glossary
System noise
Unwanted judgment variationVariability among judgments of the same case by people expected to make comparable decisions. It can be measured without knowing the correct answer, by giving multiple qualified decision makers the same cases and comparing their responses. In organizations, system noise can create inconsistent treatment, inaccurate predictions, and avoidable costs.
Noise audit
Test of judgment variationA structured study in which multiple decision makers independently assess the same cases. The spread of their responses estimates the amount of noise in a judgment system, even when the correct answer is unavailable. Audits can also reveal differences in overall severity, case-specific response patterns, and possible weaknesses in training or procedure.
Level noise
Differences in average severityThe part of system noise caused by people applying a generally higher or lower level of judgment across cases. One supervisor may routinely give stronger performance ratings, or one judge may impose harsher sentences, than colleagues do. It is measured by comparing decision makers' average judgments, not by comparing their responses to one particular case.
Pattern noise
Different reactions to casesVariation caused by decision makers responding differently to particular cases, beyond any general tendency to be strict or lenient. For example, two judges may have similar average sentence lengths but disagree about which offenses deserve harsher treatment. These distinctive response patterns can be stable, personal, and difficult to predict.
Occasion noise
Moment-to-moment judgment variationChanges in a person's judgment of the same evidence across occasions, without a relevant change in the case. Mood, fatigue, the order of previous decisions, or other incidental conditions can affect the result. It is distinct from stable differences between people, though both contribute to variation in a decision system.
Decision hygiene
Error-prevention proceduresA collection of processes intended to reduce noise before errors occur, without needing to identify the cause of each error. Examples include structuring judgments into separate assessments, using common scales, delaying first impressions, controlling the order of information, and gathering independent opinions before discussion.
Outside view
Reference-class perspectiveAn approach that estimates a case by first considering how comparable cases have turned out, then adjusting for relevant differences. It contrasts with focusing only on the details of the current case and constructing a causal story around them. In forecasting, it anchors a prediction in a base rate and limits overly extreme estimates.
Objective ignorance
Limits of available knowledgeThe portion of uncertainty in an outcome that cannot be removed by better judgment alone. It includes facts that are inherently unknowable at decision time and relevant information that could be known but is not available. It sets a ceiling on predictive accuracy and helps explain why even strong models remain imperfect.
Mediating assessments protocol
Structured option evaluationA process for evaluating complex options by dividing them into distinct, relevant assessments before reaching an overall decision. Participants define the assessments, gather evidence for each separately, use comparable reference points where possible, and submit independent ratings before discussion. Holistic judgment is delayed until the separate evidence has been reviewed.
FAQ
What's Noise: A Flaw in Human Judgment about?
- Focus on Judgment Errors: The book explores the concept of noise, which is unwanted variability in judgments, and its impact on decision-making across fields like law, medicine, and business.
- Bias vs. Noise: It distinguishes between bias, a systematic error, and noise, which is random variability in judgments that should be identical.
- Real-World Examples: The authors provide numerous examples to illustrate how noise affects decision-making processes and emphasize the need for awareness and reduction of noise.
Why should I read Noise: A Flaw in Human Judgment?
- Improve Decision-Making: The book offers insights into how understanding noise can lead to better judgments in both personal and professional contexts.
- Evidence-Based Approach: It draws on extensive research and real-world case studies, making the content credible and applicable.
- Practical Applications: The book provides actionable advice and methods for reducing noise, making it a valuable resource for professionals across different fields.
What are the key takeaways of Noise: A Flaw in Human Judgment?
- Distinction Between Bias and Noise: Understanding the difference between systematic bias and random noise is crucial for improving judgment accuracy.
- Noise Audits: The authors introduce noise audits as a method for measuring variability in judgments within organizations.
- Importance of Algorithms: Simple algorithms often outperform human judgment due to their lack of noise, challenging the belief in human intuition's superiority.
How does Noise: A Flaw in Human Judgment differentiate between bias and noise?
- Bias Defined: Bias refers to systematic errors in judgment that consistently push decisions in one direction.
- Noise Explained: Noise is the random variability in judgments that should be the same, leading to inconsistent outcomes.
- Impact on Decision-Making: Addressing noise requires different strategies than addressing bias, making this distinction crucial for improving decision processes.
What is a noise audit, and how is it conducted in Noise: A Flaw in Human Judgment?
- Definition of Noise Audit: A noise audit is a systematic evaluation of the variability in judgments made by professionals within an organization.
- Methodology: It involves presenting the same cases to multiple judges and analyzing the differences in their judgments.
- Outcomes: The results can reveal significant discrepancies, prompting organizations to address noise and implement improvement strategies.
What is decision hygiene as described in Noise: A Flaw in Human Judgment?
- Preventive Approach: Decision hygiene refers to practices that aim to reduce noise in decision-making processes.
- Structured Processes: It involves structuring judgments into smaller, independent tasks and delaying holistic judgments until all components have been evaluated.
- Focus on Accuracy: The goal is to enhance the accuracy of judgments by minimizing variability caused by individual biases and cognitive errors.
How does noise affect decision-making in medicine according to Noise: A Flaw in Human Judgment?
- Variability in Diagnoses: Different doctors can arrive at varying diagnoses for the same patient, highlighting noise in medical judgments.
- Impact on Patient Care: High levels of noise can lead to misdiagnoses and inconsistent treatment recommendations.
- Case Studies: Examples from medical practice illustrate how noise manifests in areas like radiology and psychiatry.
How do algorithms compare to human judgment in predictive tasks in Noise: A Flaw in Human Judgment?
- Superiority of Algorithms: Algorithms, particularly simple models, often outperform human judgment due to their lack of noise.
- Examples of Success: The book provides examples where algorithms have successfully predicted outcomes in fields like finance and healthcare.
- Implications for Professionals: Professionals are encouraged to integrate algorithmic approaches to enhance accuracy and reduce noise.
What is the mediating assessments protocol mentioned in Noise: A Flaw in Human Judgment?
- Structured Evaluation Process: It is a structured approach to decision-making that breaks down complex judgments into independent assessments.
- Independent Assessments: Each assessment is evaluated separately to minimize biases and ensure objective criteria.
- Delayed Holistic Judgment: Final decisions are made only after all assessments, allowing for a more informed conclusion.
What strategies can be implemented to reduce noise in decision-making according to Noise: A Flaw in Human Judgment?
- Decision Hygiene: Practices like standardizing procedures, using checklists, and implementing noise audits are recommended.
- Training and Education: Training professionals on the impact of noise and bias can improve decision-making practices.
- Use of Algorithms: Integrating algorithms into decision-making processes can help reduce noise and enhance accuracy.
What are the different types of noise discussed in Noise: A Flaw in Human Judgment?
- Level Noise: Variability in the average severity of judgments made by different individuals.
- Pattern Noise: Differences in how individuals respond to specific cases, reflecting unique biases and perspectives.
- Occasion Noise: Variability in judgments made by the same individual at different times, influenced by mood and circumstances.
What are the best quotes from Noise: A Flaw in Human Judgment and what do they mean?
- “Wherever there is judgment, there is noise—and more of it than you think.”: Emphasizes that noise is a pervasive issue in decision-making.
- “The rule of law calls for a body of impersonal rules, applicable across the board.”: Advocates for standardized decision-making processes to reduce noise.
- “You are not the same person at all times.”: Highlights occasion noise, reminding readers of the variability in individual judgments.
About the Author
Other books by Daniel Kahneman

Download PDF
Download EPUB
.epub digital book format is ideal for reading ebooks on phones, tablets, and e-readers.








